Contents
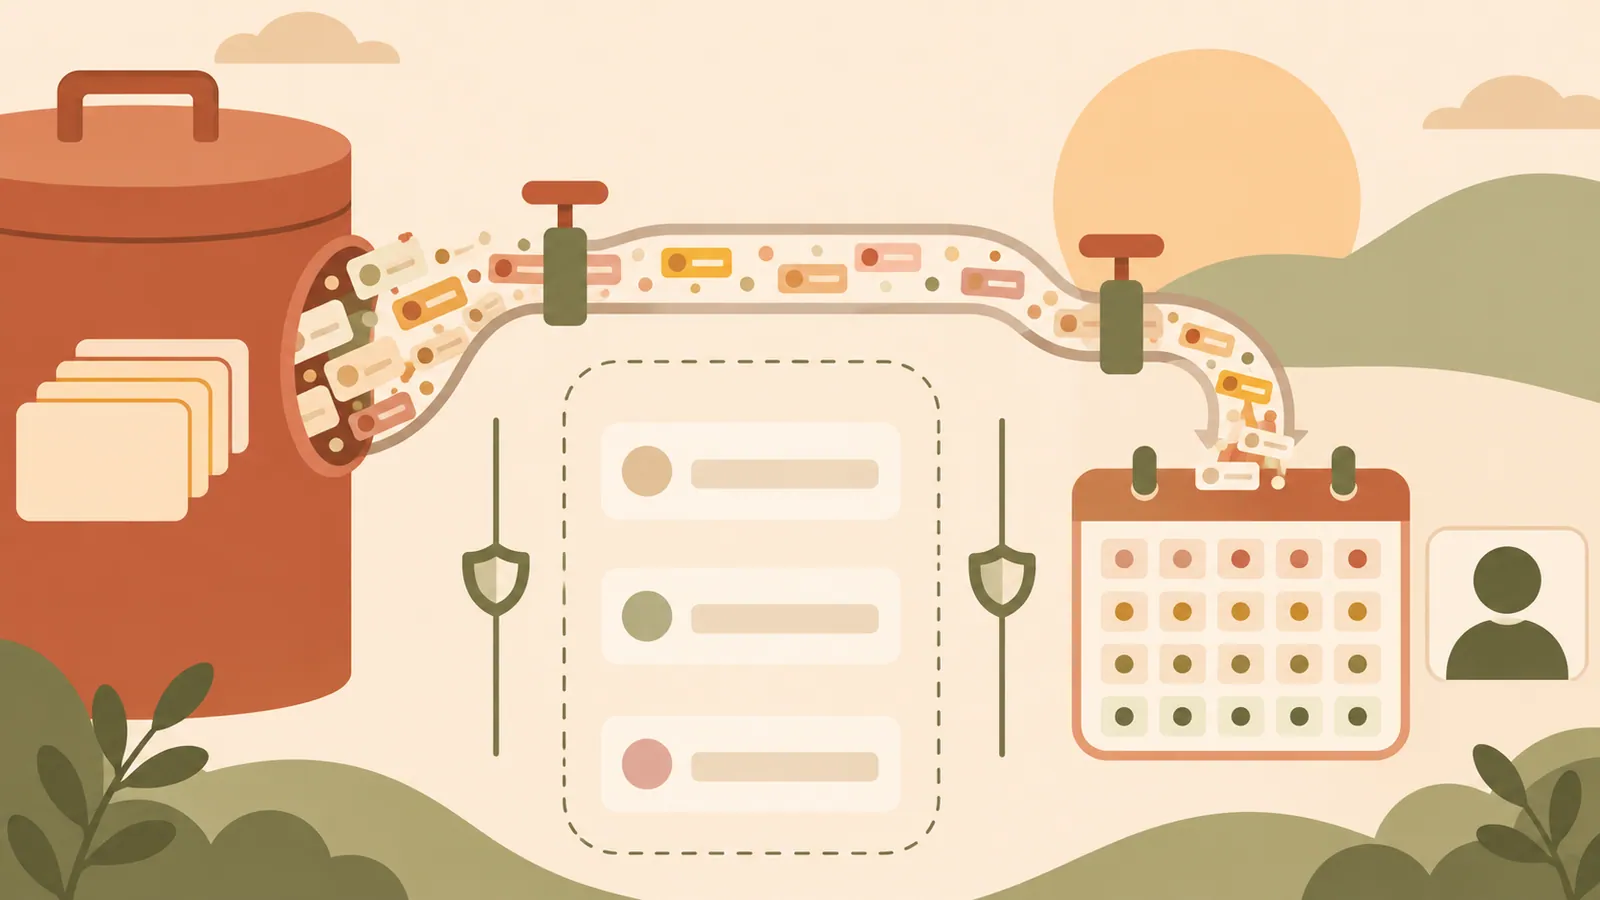
mixi2’s X archive importer adds past posts to the calendar and profile while suppressing timeline distribution, notifications, and posting-streak updates. The main technical challenge was preserving records while controlling the side effects of creating thousands of posts.
Key points#
- Imported posts retain their original X timestamps and appear on the corresponding calendar dates.
- Large archives upload directly to S3, with preparation and post creation handled asynchronously.
- Post data is split into chunks of up to 1,000 posts, with one chunk queued at a time per import.
- Duplicate prevention and separate counts for successes, failures, and skipped posts make retries easier to manage.
Define what importing means#
Imported posts should be treated as historical records. mixi2 displays them in the calendar and profile, but does not distribute them to followers’ home timelines, send post notifications, or increment users’ posting streaks. They are also intended to appear in search, but handling their timestamps required additional work.
The importer excludes replies and reposts. Quote posts are converted into the user’s own text and a link, without recreating the original conversation structure. X mentions remain plain text because someone using the same username on mixi2 could be a different person. Converting them into active mentions could notify the wrong person.
These rules establish a practical boundary: reuse existing storage and media processing while explicitly controlling every action triggered by post creation. Simply backdating posts does not prevent notifications or feed distribution.
Read and normalize the archive#
The relevant archive files are data/tweets.js, all files matching tweets-part*.js, and attachments in data/tweets_media/. Although the post files have a .js extension, they contain JSON data assigned to a JavaScript variable. Removing the assignment wrapper allows the records to be parsed as JSON.
Each record contains an X post ID, timestamp, and text. The text needs normalization: expand t.co links using the associated URL fields and decode HTML entities such as &. For images examined during development, combining the post ID with the filename from the media URL identified the corresponding file in the archive.
Videos require matching candidate URLs against files actually present in the ZIP. Some attachments displayed as GIFs on X are MP4 files in the archive. This means inspecting the actual files rather than assuming their format from the display label.
Process large ZIP files in stages#
This design anticipates archives of tens of gigabytes. The source includes user reports of separate downloads estimated at 50 GB and 15 GB. These reports justify preparing for large files; they do not establish official X archive sizes or partitioning.
Processing proceeds in four stages.
1. The client uploads the ZIP directly to S3 using multipart upload, allowing failed parts to be retried. 2. An upload-completion event starts a preparation worker, allowing processing to continue after the user closes the screen. 3. The worker accesses the ZIP using S3 Files and Go’s zip.OpenReader, reading the required entries without holding the entire archive in application memory. 4. Extracted media and normalized post data are saved to S3, with post data split into JSONL files containing up to 1,000 posts each.
Each JSONL line represents one post. Chunking limits the number of posts created per job and the scope of retries. Only the first chunk is queued initially; the next is queued when it finishes. This prevents all the chunks from one large import from filling the shared queue, while workers control overall concurrency.
Preserve records within the limits#
The source states that mixi2’s character limit is 149.3 characters. Some X posts exceed this limit, so their text is shortened and an ellipsis and a link to the original post are added. The resulting character count must remain within the destination’s limit.
Media has separate size and duration limits. If an attachment fails a condition that can be checked in advance, the importer retains the text and media that meet the requirements and adds a link to the original post. Even if multiple attachments cannot be imported, the link is added only once per post.
This fallback preserves access to omitted content, provided the original X post remains available. Media conversion errors during processing are treated as failures, rather than handled like known size or duration limits.
Make retries safe and results clear#
The importer records a mapping between each X post ID and the mixi2 post ID it creates. On retries, it checks this mapping and skips posts already imported by the same user. Post creation and insertion of the mapping run in a single database transaction, preventing saved posts from lacking an import record.
One failed post does not stop all subsequent posts. Successes, failures, and skipped posts are counted separately, and results are reported after the final chunk is processed. An import reaching the end therefore does not mean every record succeeded.
Timestamp checks must also extend to downstream systems. According to the source, additional work was still needed to place imported posts in search results according to their original dates. Correct ordering in the calendar and profile does not guarantee correct ordering in search.
Next steps#
Before building an archive importer, create a table defining how imported posts should behave with respect to timestamps, feeds, notifications, search, and activity counters.
Source: https://zenn.dev/mixi/articles/bcf2363e83b0a2
Contents