Contents
Use decision models when your application needs predefined answers, such as a department to route an inquiry to or an urgency score. Hugging Face’s decision interface returns typed results and probabilities without generating text responses, allowing you to evaluate predefined options consistently.
Key Points#
- Define the input state and allowed answers, then use the returned probabilities to control application behavior.
- Use
choicefor options,scorefor ordered levels, andnoulfor yes/no probabilities. - Supported Transformers and llama.cpp implementations provide the
/v1/systemoneendpoint. - Validate accuracy, probability calibration, and latency on your own data before automating decisions.
When to Use Decision Models#
Decision models suit tasks where the application already knows the possible answers. Examples include routing support tickets, prioritizing reviews, determining whether a message requests a refund, and choosing among available tools.
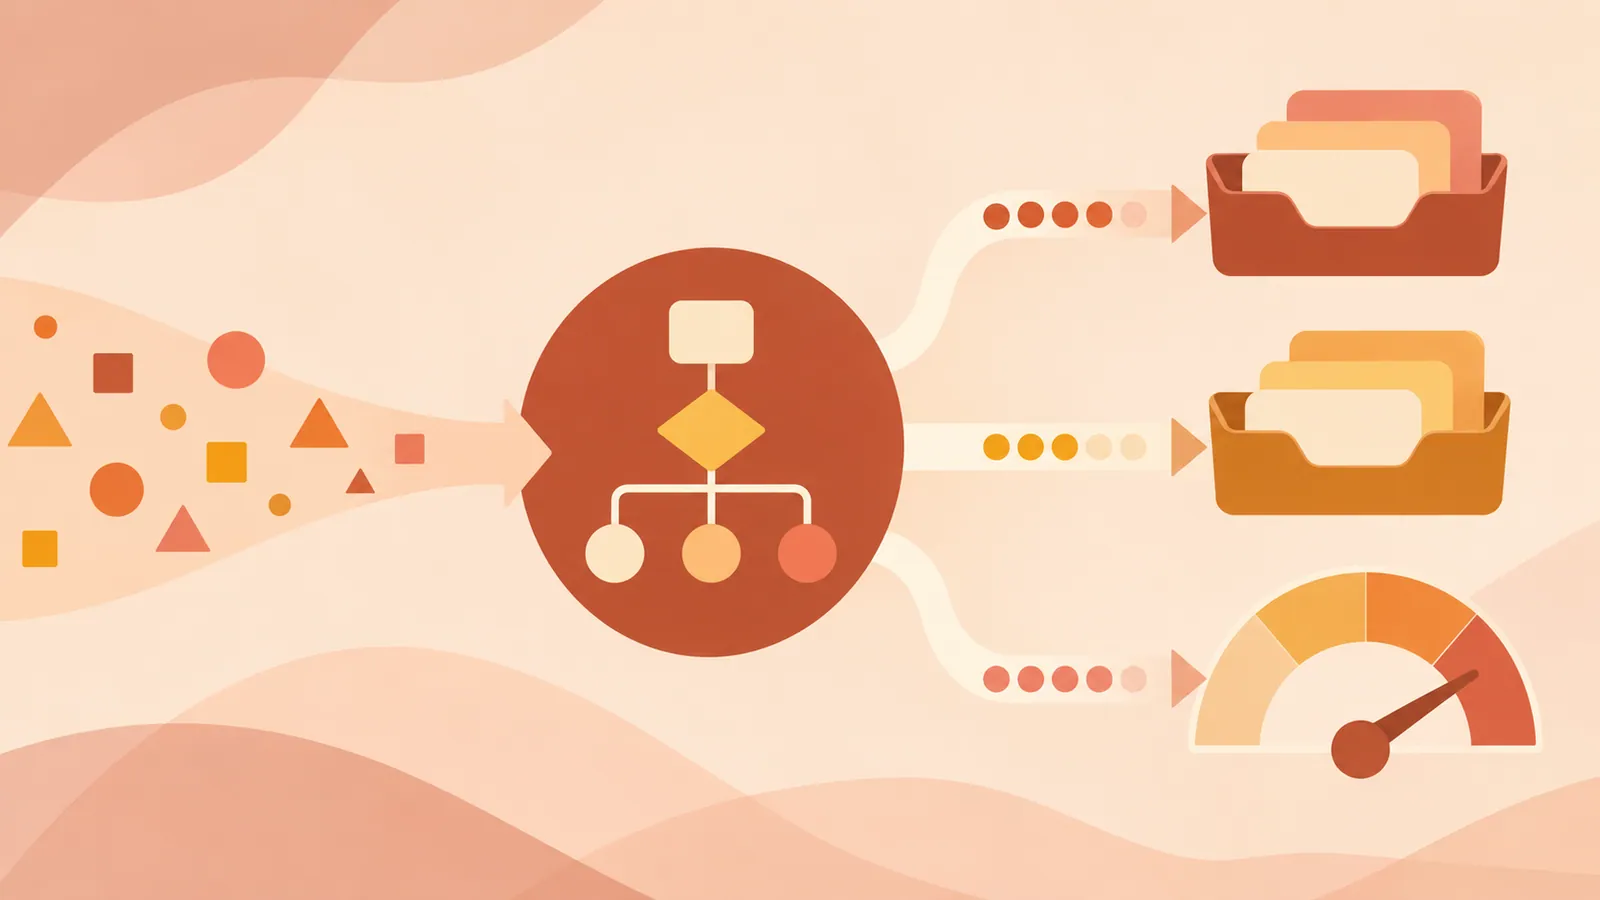
The interface is simple: state + question + allowed answers → decision + probabilities. A single request can include multiple named questions about the same input. The application receives structured values ready to use.
This overlaps with classification. Fixed-label classifiers already return probabilities, and zero-shot classifiers already support specifying labels at inference time. The practical difference is a shared interface across multiple question formats. Continue using text generation for tasks that require free-form output, such as explanations and draft replies.
Define Answer Types#
Choose the primitive type that fits the decision. Describe categories clearly, and distinguish ordered levels sufficiently for reviewers to apply them consistently.
| Primitive Type | What You Define | What Is Returned | |---|---|---| | choice | Options with names and descriptions | The selected option and the probability of each option | | score | An ordered list of criteria | The expected value of the level index and its probability distribution | | noul | A yes/no question | The model’s estimated probability that the answer is “yes” |
If urgency levels are 0, 1, and 2, with probabilities of 0.02, 0.26, and 0.72, the score is 1.70: 0 × 0.02 + 1 × 0.26 + 2 × 0.72. This is an average based on the distribution, rather than a selected category. A noul value of 0.92 means a 92% probability of “yes.” The application decides whether that is sufficient to act.
Run Your First Request#
In an environment with a supported version of Transformers, load the decision pipeline and define one question. This example follows the interface described in Hugging Face’s November 10, 2026 announcement. Check package support and the model’s hardware requirements before running it.
from transformers import pipeline

decide = pipeline(
    "decision",
    model="autotrust/GEV-26B-Decide",
)

result = decide({
    "state": "二重に請求されたので返金してほしいです。",
    "questions": {
        "department": {
            "type": "choice",
            "instructions": "どのチームが対応すべきですか?",
            "criteria": {
                "billing": "支払いと返金",
                "technical": "バグと技術的な問題",
                "sales": "料金とサブスクリプション",
            },
        },
    },
})

print(result)
Inspect the selected department and the full distribution before integrating the results into your workflow. Verify that the routing criteria work on representative examples, then add questions about urgency or refunds. Adding categories at inference time makes the interface flexible, but does not guarantee that the model can reliably recognize those categories.
Serve Through a Common API#
For HTTP integration, supported Transformers serving implementations and llama.cpp implementations use /v1/systemone. Requests include state and questions, while model selection depends on the server configuration. You can find supported models using the decision-model tag on the Hugging Face Hub.
A common specification reduces integration work when switching models or inference engines. It does not guarantee identical predictions, supported modalities, or performance. Transformers also makes this interface available to supported autoregressive models by evaluating answer-label logits without generating a response.
Generating no output tokens does not eliminate inference costs. Input processing, model size, question count, and implementation still affect latency and memory usage. Measure the entire request and compare it with existing classifiers and LLMs that produce structured output.
Check Confidence Before Automating#
A concentrated probability distribution can still produce an incorrect decision. The documented confidence measure for choice normalizes the maximum probability relative to a uniform distribution. With four options and a highest probability of 0.85, confidence is 0.80. This measures concentration, not validated accuracy. Do not assume the same calculation applies to score.
Before deployment, check these four things.
- Measure decision accuracy on labeled examples from real operations.
- Check calibration. Predictions with probabilities near 0.90 should be correct about 90% of the time.
- Include ambiguous inputs and cases that fit none of the allowed answers.
- Compare latency and resource usage under the same deployment conditions.
Use those results to set thresholds for human review. Automatically routing a ticket and approving a refund, for example, have different consequences. Detecting a refund request alone should not authorize a payment.
Next Steps#
Create a labeled evaluation set from 100 real support tickets, and compare department routing accuracy and latency with your current system before enabling automatic routing.
Source: https://huggingface.co/blog/decision
Contents